About VideoInPrompt
What is VideoInPrompt?
VideoInPrompt is a cutting-edge multimedia application designed to bridge the gap between visual media and large language models. It specializes in analyzing video content frame-by-frame to generate highly descriptive text prompts, translating visual elements such as motion, lighting, and subjects into structured data. This enables creators to repurpose video for various AI generation tools, making it an essential resource for digital marketers, video editors, content creators, and developers.
What sets VideoInPrompt apart is its true multimodal engine that goes beyond basic transcription tools. It extracts cinematic narratives, motion vectors, and structured JSON metadata, processing video frames in seconds while ensuring that users' intellectual property remains secure. With its uncompromising speed and efficiency, VideoInPrompt accelerates workflows by allowing users to generate SEO-optimized articles, shot lists, and more from their video content.
Instant conversion of visual references into text instructions
Extraction of cinematic narratives and structured metadata
Fast processing of video frames with a stateless infrastructure
Designed for a variety of users including marketers and content creators
VideoInPrompt Features
VideoInPrompt is a cutting-edge multimedia application designed to transform video content into structured text prompts. It utilizes advanced technology to analyze video frame-by-frame, extracting essential elements such as motion, lighting, and subjects. This capability allows creators to repurpose video for various AI generation tools, enhancing their workflow and productivity.
What sets VideoInPrompt apart from traditional transcription tools is its true multimodal engine, which not only transcribes but also extracts cinematic narratives, motion vectors, and structured JSON metadata. The platform operates with uncompromising speed, processing video frames in seconds while ensuring that users' intellectual property remains secure and is not used to train its models.
Frame-by-frame video analysis for detailed text prompt generation
Extraction of cinematic narratives and motion vectors
Structured JSON metadata output for easy integration with AI tools
Stateless processing to protect user intellectual property
Designed for digital marketers, video editors, content creators, and developers
Why VideoInPrompt?
VideoInPrompt offers a unique value proposition by serving as a true multimodal engine that goes beyond basic transcription tools. It extracts cinematic narratives, motion vectors, and structured JSON metadata, enabling users to harness the full potential of their video content. This capability allows for rapid processing of video frames, ensuring that users can access critical insights in seconds while maintaining the confidentiality of their intellectual property.
By utilizing VideoInPrompt, users can experience several key benefits:
Uncompromising speed in processing video data, saving valuable time.
Intelligent sampling of keyframes to capture essential moments without redundancy.
State-of-the-art vision models that evaluate scenes for comprehensive context.
Synthesis of analyzed data into natural language or structured JSON for seamless integration into automated workflows.
How to Use VideoInPrompt
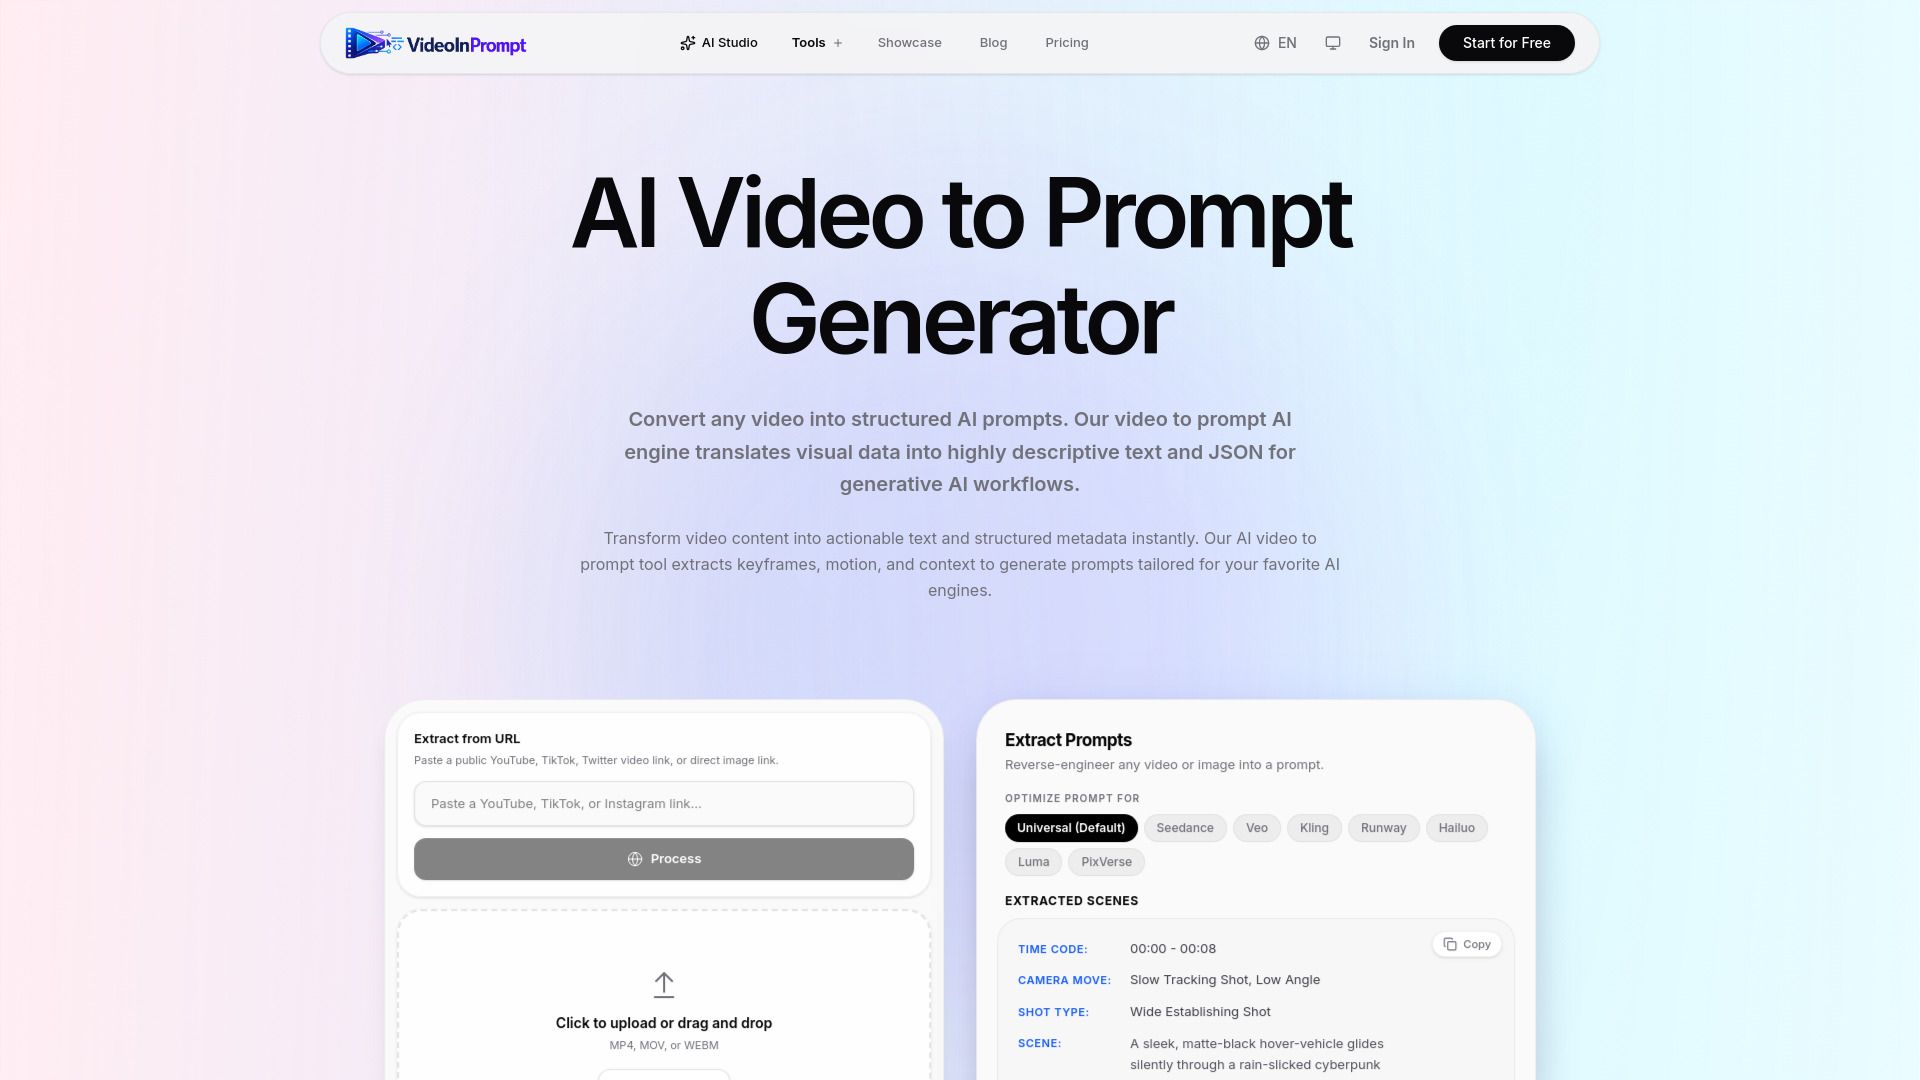
Getting started with VideoInPrompt is simple and user-friendly. To begin, you can upload your video by dragging and dropping it into the designated area or by clicking to select the file. Once your video is uploaded, our AI will analyze it frame-by-frame to generate descriptive text prompts that can be used for various applications.
For a smooth experience, here are some key features to explore:
Instant video analysis for prompt generation
Support for cinematic narratives and structured JSON metadata
Upgrade options for processing longer videos and obtaining additional data formats
Ready to see what VideoInPrompt can do for you?and experience the benefits firsthand.
Key Features
How to Use
Visit the Website
Navigate to the tool's official website.
Pros & Cons
What's good
What's not good
Pricing
- Max 15s per video
- 10 free credits
- 50MB max file size
- Basic AI Models
- 100 Credits / month
- Standard AI Models
- Full Video Processing
- 2GB max file size
- 100 Credits / month
- Standard AI Models
- Full Video Processing
- 2GB max file size
- 400 Credits / month
- Premium AI Models
- Advanced Styles & Storyboards
- 10GB max file size
- Highest Queue Priority
- 400 Credits / month
- Premium AI Models
- Advanced Styles & Storyboards
- 10GB max file size
- Highest Queue Priority
- Valid for extraction & generation
- Ideal for one-off workflows
- Credits never expire
- Balanced for regular creators
- Unlocks both extraction & generation
- Credits never expire