Seed Audio 1.0
Create dialogue, expressive voices, ambience, music, and sound effects from text, image, or audio prompts with Seed Audio 1.0 online.
- Monthly visits
- 8.5K
- Pricing
- Freemium
- Free, Pro, Max
- Added
- 2026-08-19 10:48:06
About Seed Audio 1.0
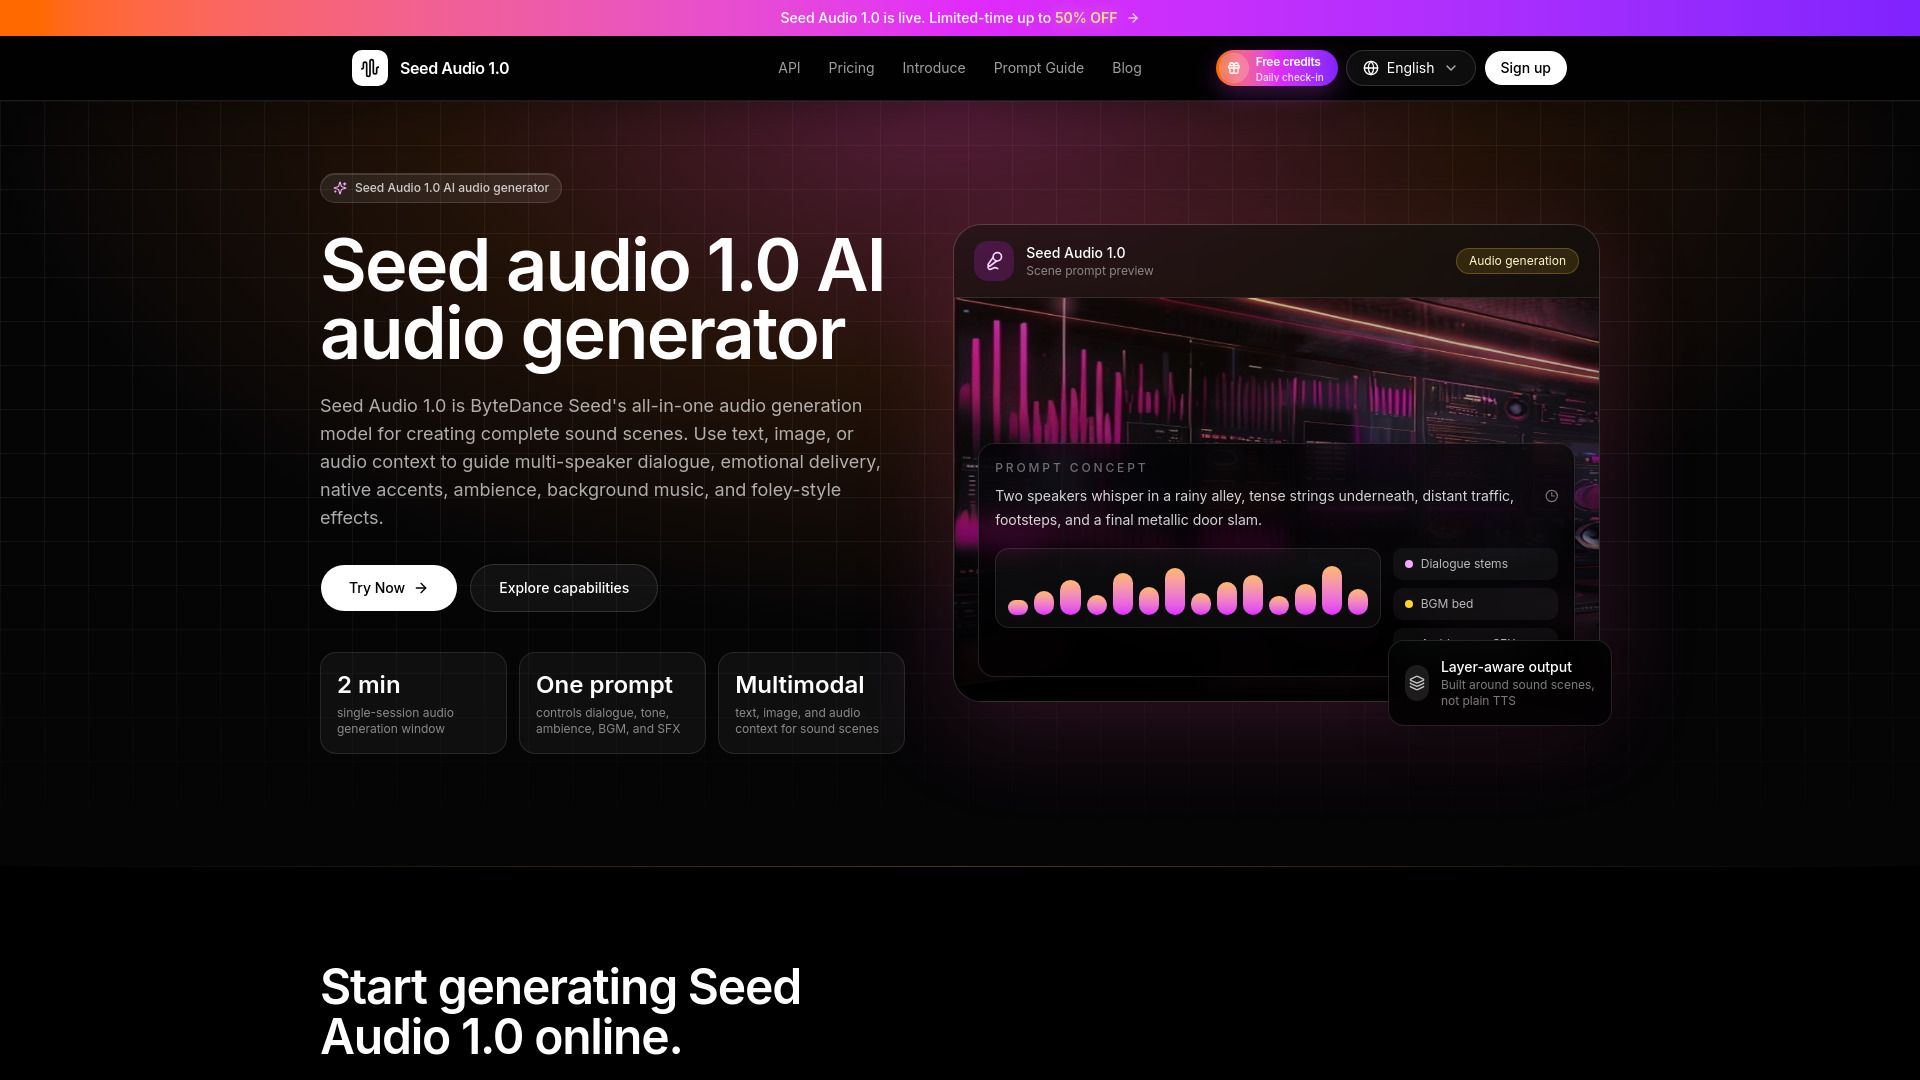
Seed Audio 1.0 is ByteDance Seed's multimodal AI audio generation model for building complete sound scenes from text, image, and audio inputs. In one workflow, it can combine multi-speaker dialogue, expressive voices, native accents, ambience, background music, and foley-style sound effects instead of producing speech alone.
Prompts can describe speakers, timing, emotion, language, location, music direction, and sound events together. This makes the model useful for cinematic scenes, localized dialogue, ads, podcasts, games, and other projects where voice and the surrounding soundscape need to work as one.
Inputs: Text, image, and up to 3 audio references; Sound layers: Dialogue, voice, ambience, music, and sound effects; Output: One coordinated audio scene up to 2 minutes.
How to use: write a sound-scene prompt, optionally add an audio or image reference, choose output settings, then generate and review the audio in the SeedAudio.co workspace.
Use cases
- Scene Sound & Foley for short dramas, food videos, and AI video post-production.
- AI Music to produce original soundtracks and background music for films, ads, and regional formats.
Key features
- Multimodal prompts for audio creation
- Layered sound design in one pass
- Output one coordinated audio scene up to 2 minutes
- Voice and mood control across scenes
- Reference-guided texture and consistency
Pros and cons
Pros
Pricing
- 10 free credits
- Up to ~8 seconds per generation
- Max 2 min audio per generation
- API access
- Priority support
- 30,000 credits / year
- Up to ~400 total audio minutes
- Reference voice uploads
- Priority support
- Max 2 min audio per generation
- Seed Audio 1.0 API access — shared credits
- 90,000 credits / year
- Up to ~1,200 total audio minutes
- Everything in Pro
- Team and agency-friendly usage
- Max 2 min audio per generation
- Seed Audio 1.0 API access — shared credits
Reviews
Frequently asked questions
What inputs does Seed Audio 1.0 support?
How long can each generation be?
Can I use output commercially?
Alternatives to Seed Audio 1.0
More in AI Sound Effect GeneratorSongburst
Songburst is an AI music generator that turns words into original songs for content use, with unlimited downloads and export options.
SongGuru.AI
SongGuru.AI provides an AI Song Generator to create music from lyrics or prompts for commercial use.

Narrative Nooks
Narrative Nooks provides AI-driven, story-based learning and 24/7 tutoring for young learners, with personalized tutoring and badge rewards.

Vip.graphics
Instant generates editable, visually engaging presentations directly in Google Slides for users who need fast, AI-assisted deck creation.